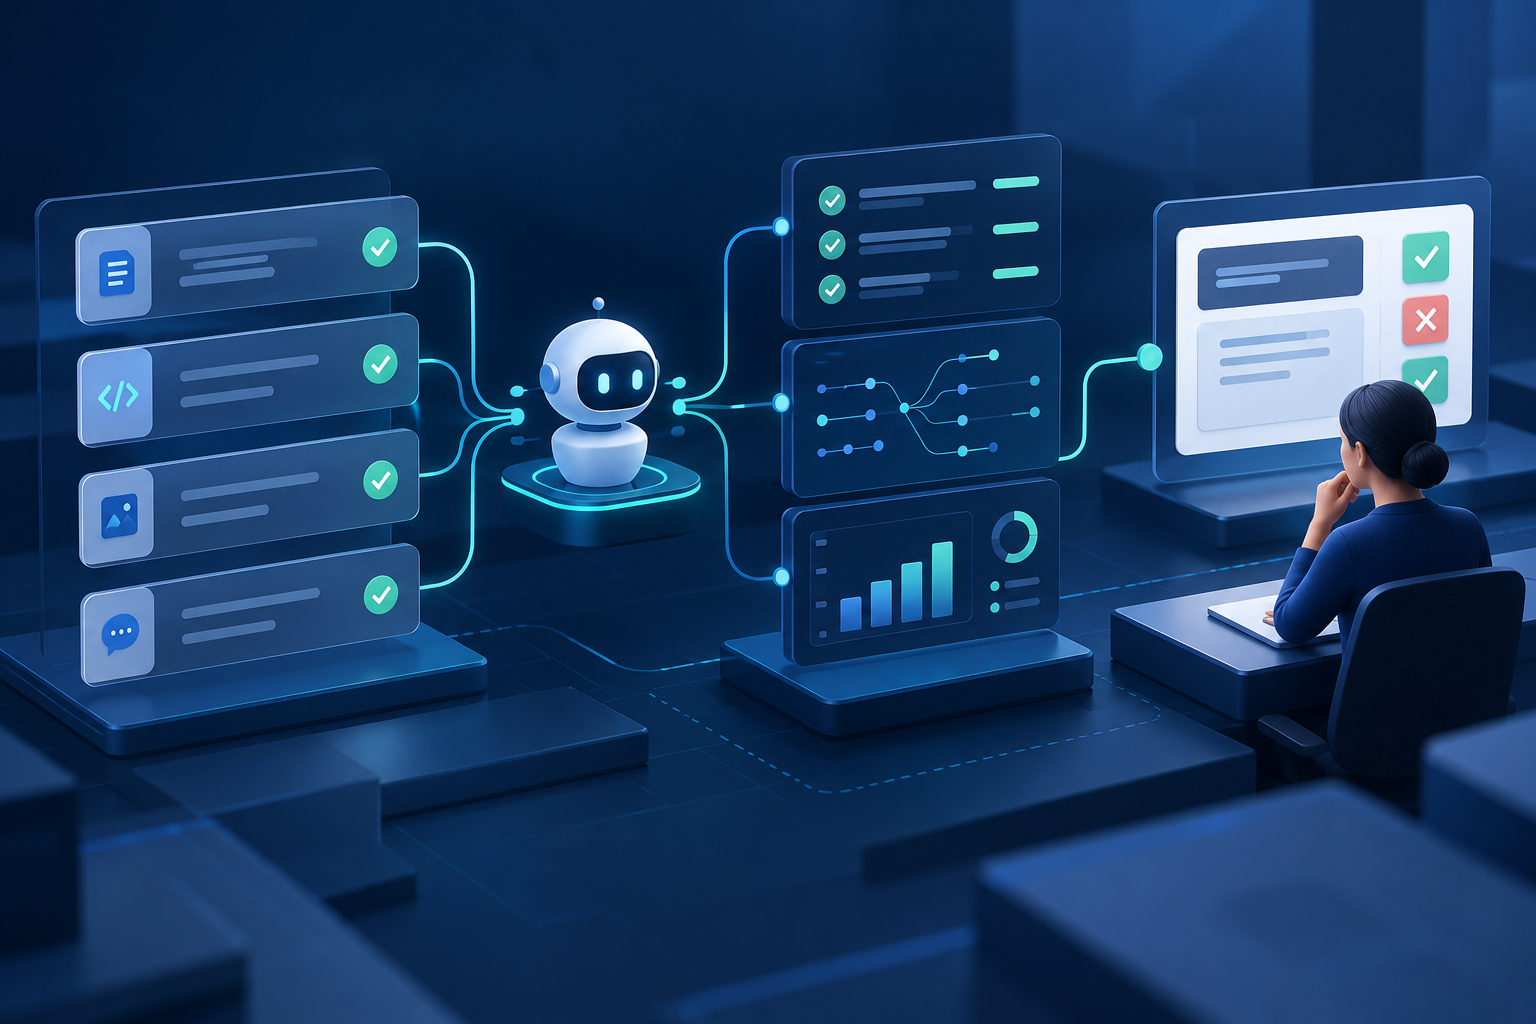
An AI agent evaluation framework is a repeatable set of cases, metrics, and release decisions for a workflow that can reason, retrieve information, or call tools. It should test the behavior that matters to the business, not only whether a demo response sounds fluent. A useful framework combines task success, grounding, correct tool use, authorization, escalation quality, latency, and cost.
What should an AI agent evaluation measure?
- Task outcome: Did the workflow reach the intended state?
- Evidence use: Did the agent rely on approved, relevant context?
- Tool behavior: Did it select the right tool and arguments?
- Safety: Did it refuse or escalate when authority or evidence was missing?
- Operations: Did it stay within latency, cost, and retry limits?
How do you build a representative evaluation set?
Start with real workflow categories and add deliberate edge cases. Include complete requests, ambiguous inputs, missing records, conflicting sources, permission failures, duplicate events, unavailable tools, prompt injection, and sensitive-data requests. Keep each case tied to an expected outcome and an explanation of what evidence a reviewer should see.
Which tests belong in every release?
Run deterministic checks for schema validity, required fields, authorization decisions, tool allowlists, and idempotency. Use rubric-based review for summaries, classifications, and grounded responses. Replay a fixed regression set whenever the model, prompt, retrieval source, tool contract, or policy changes. Separate offline evaluation from a staged environment that exercises real integrations with safe data.
How should evaluation affect autonomy?
Evaluation results should determine the workflow mode. A low-risk score may support suggestions or drafts, while a higher-risk action should require stronger evidence and explicit approval. Do not turn a passing average into unrestricted autonomy. Inspect the failures that could create financial, privacy, operational, or customer harm, even when they are rare.
What should a production release gate include?
Require an owner, a versioned evaluation set, minimum thresholds for critical behaviors, trace coverage, rollback or disable controls, and a human escalation path. DeepVention Labs helps teams build AgentOps evaluation and observability into the workflow before it is exposed to real users.
Build an LLM GTM system around this topic.
Explore strategy, GEO content, proof architecture, distribution, automation, and visibility measurement.